ios-arch-kit
Architecture guardrails for agentic coding
A portable kit that encodes iOS architectural conventions as machine-readable constraints an agent reads before writing code. Conventions were extracted from a production reference codebase across six structured passes under a hard evidentiary rule: every claim cites a real file path, nothing generalised from a single occurrence, no invented principles. Claims are tagged evidenced or extrapolated, and the ratio is tracked as a quality metric.
Ships as an always-on specification under 60 lines, an architecture skill with a reference directory, an installer, and documentation of the extraction passes.
How I know it works
I evaluated the kit blind, guided against unguided.
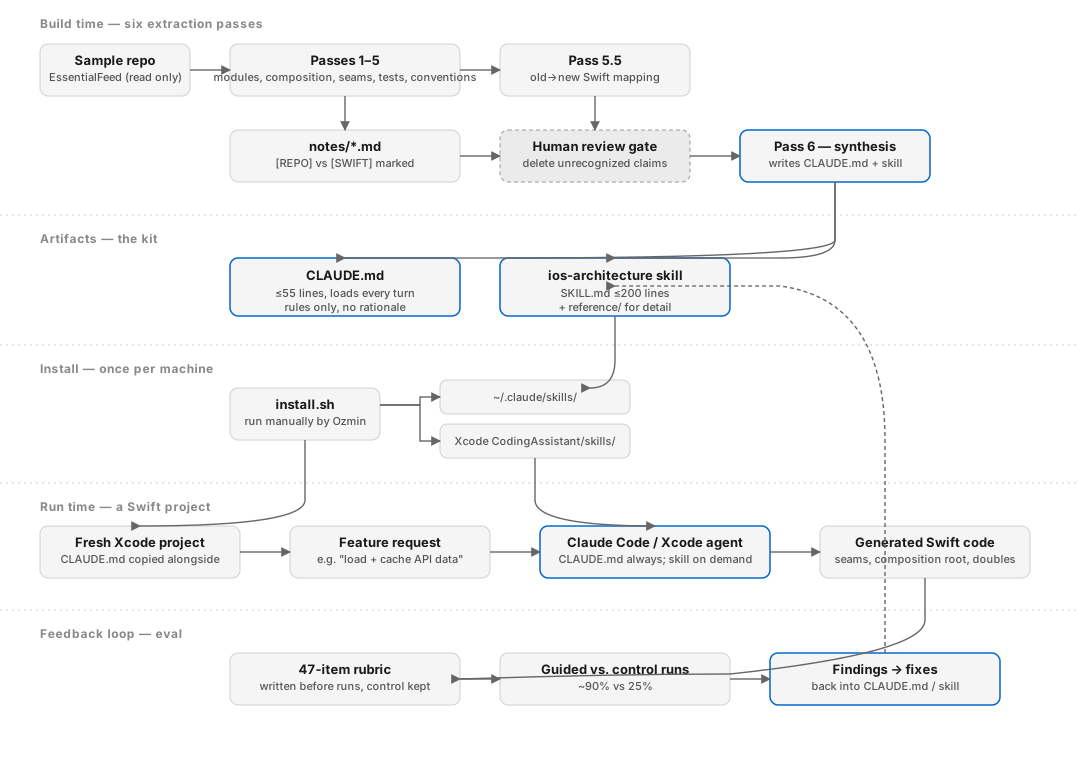
The ios-arch-kit pipeline in five stages. Build time: the EssentialFeed sample repo is read by six extraction passes into notes files, gated by human review, then synthesised into CLAUDE.md and a skill. Artifacts: CLAUDE.md and the ios-architecture skill. Install: install.sh links the skill into Claude Code and Xcode. Run time: a fresh Swift project loads CLAUDE.md every turn and the skill on demand, producing generated code. Feedback loop: a 47-item rubric compares guided against control runs, and findings feed back into the kit.
The scorecard matters as much as the headline number. I ran the kit's architectural predictions against a real async/await migration in the reference repository, then turned the hit rate into a calibration rule applied to the remaining claims. Predicting where you will be wrong, and pricing it, is the part that generalises.
When it goes wrong
During the extraction I caught a fabricated statistic that had already propagated through three hops of generated files. I logged it as evidence for mandatory human review gates. I also caught my own error: I had briefed the agents with the wrong baseline commit, twice. Two agents flagged it, and the real baseline was established by CI-workflow blob match plus file modification times.
Both incidents are in the record on purpose. “How do you handle AI reliability?” deserves a real answer with a root cause and a process change, not a reassurance.
A defended position. Storage ports are synchronous throws; network ports are async throws. A store protocol never says async, never says @MainActor, and never names a queue — asynchrony is injected above it, and the composition root absorbs the churn. Verified against the repository's real concurrency migration: the seam modelling a domain capability survived; the seam modelling a concurrency mechanism was deleted by the new mechanism.